Raven Max vs GPT-5.6 Sol and Fable 5: the head-to-head numbers
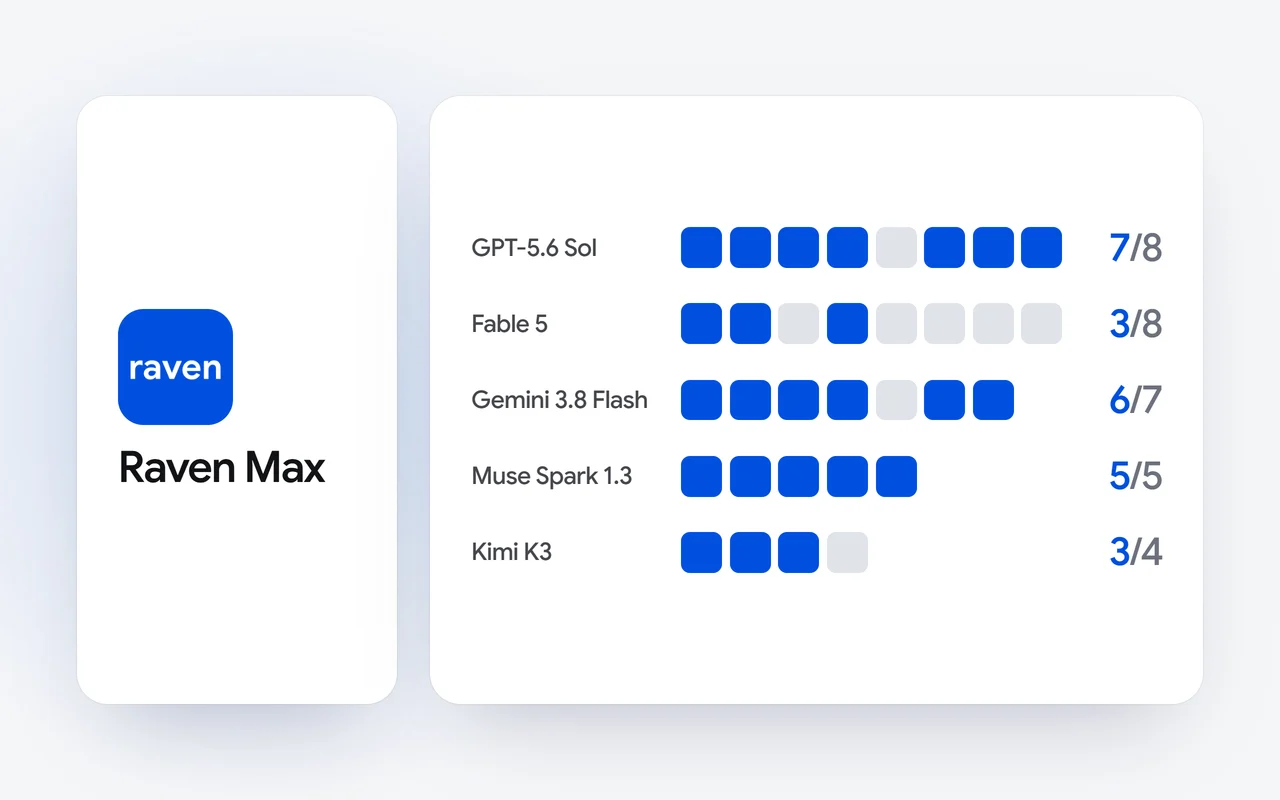
Raven Max is first among the models compared on Terminal Bench 4.0, Agent's Last Exam and GDPVal-AA in our published results. Head to head, it is ahead of GPT-5.6 Sol on seven of eight tests and of Gemini 3.8 Flash on six of the seven they share; Fable 5 is ahead of it on five of eight.
Key facts
- First among the models compared on Terminal Bench 4.0 (42.8), Agent's Last Exam (39.5) and GDPVal-AA (1,771).
- Against GPT-5.6 Sol: ahead on 7 of 8 tests; GPT-5.6 Sol is ahead on DeepSWE v1.1.
- Against Fable 5: ahead on 3 of 8; Fable 5 is ahead on the other 5.
- Ahead of Gemini 3.8 Flash on 6 of 7, Muse Spark 1.3 on 5 of 5 and Kimi K3 on 3 of 4 shared tests.
- Company-reported results from our technical report (October 2026), every test evaluated with maximum reasoning effort.
Raven Max is our flagship reasoning model. Our report on Raven Max lists its eight results and where each one places. This piece reads the same results the other way round: one model at a time, as a head-to-head scorecard. The results are company-reported, from our technical report of October 2026, and every test was evaluated with maximum reasoning effort.
Where is Raven Max first?
On three of the eight tests, Raven Max scores higher than every model it is compared with:
- Terminal Bench 4.0: 42.8, 0.4 ahead of Fable 5 (42.4)
- Agent's Last Exam: 39.5, 7.9 ahead of Fable 5 (31.6)
- GDPVal-AA: 1,771, 11 ahead of Fable 5 (1,760)
All three are tests of work that runs over many steps: autonomous software engineering in a live terminal, long-horizon agentic reasoning, and real economic tasks. That is the work Raven Max is built for. On each of the three, the nearest model is Fable 5.
How does Raven Max compare with GPT-5.6 Sol and Fable 5, test by test?
GPT-5.6 Sol and Fable 5 are the two models that appear beside Raven Max on all eight tests. Here are the three side by side, with the highest of the three on each test in bold.
| Benchmark | Raven Max | GPT-5.6 Sol | Fable 5 |
|---|---|---|---|
| Terminal Bench 4.0 | 42.8 | 37.9 | 42.4 |
| Agent's Last Exam | 39.5 | 29.8 | 31.6 |
| Automation | 48.3 | 44.0 | 48.6 |
| GDPVal-AA | 1,771 | 1,730 | 1,760 |
| Deep | 68.7 | 70.2 | 69.7 |
| Intelligence Index | 47 | 44 | 50 |
| HLE w/ Tools | 62.8 | 58.5 | 63.2 |
| AA-Briefcase v1.1 | 1,522 | 1,520 | 1,539 |
Against GPT-5.6 Sol, Raven Max is ahead on seven of the eight. Against Fable 5, it is ahead on three, and Fable 5 is ahead on the other five. The chart below adds the other three models, each counted on the tests it shares with Raven Max.
Tests on which Raven Max scores higherof the tests both took
| Model compared | of the tests both took |
|---|---|
| GPT-5.6 Sol (8 tests) | 7 |
| Gemini 3.8 Flash (7 tests) | 6 |
| Muse Spark 1.3 (5 tests) | 5 |
| Fable 5 (8 tests) | 3 |
| Kimi K3 (4 tests) | 3 |
Evaluated with maximum reasoning effort enabled. Source: Dipole ML Inc. Technical Report (October 2026).
How does Raven Max compare with GPT-5.6 Sol?
Raven Max is ahead of GPT-5.6 Sol on seven of the eight tests: Terminal Bench 4.0 (42.8 to 37.9), Agent's Last Exam (39.5 to 29.8), AutomationBench (48.3 to 44.0), GDPVal-AA (1,771 to 1,730), Intelligence Index (47 to 44), HLE w/ Tools (62.8 to 58.5) and AA-Briefcase v1.1 (1,522 to 1,520).
GPT-5.6 Sol is ahead on DeepSWE v1.1 (70.2 to 68.7), a gap of 1.5, and is first among the models compared on that test.
How does Raven Max compare with Fable 5?
Fable 5 is the one model in our results that is ahead of Raven Max on more tests than it is behind: five of the eight.
Raven Max is ahead on Terminal Bench 4.0 (42.8 to 42.4), Agent's Last Exam (39.5 to 31.6) and GDPVal-AA (1,771 to 1,760). Fable 5 is ahead on AutomationBench (48.6 to 48.3), DeepSWE v1.1 (69.7 to 68.7), Intelligence Index (50 to 47), HLE w/ Tools (63.2 to 62.8) and AA-Briefcase v1.1 (1,539 to 1,522).
On three of those five tests, Raven Max is second, behind Fable 5 alone. AutomationBench is one of them.
A bar chart of five scores on AutomationBench, with Fable 5 first at 48.6 and Raven Max second at 48.3.
AutomationBenchScore
| Model | Score |
|---|---|
| Fable 5 | 48.6 |
| Raven Max | 48.3 |
| Kimi K3 | 46.7 |
| GPT-5.6 Sol | 44.0 |
| Gemini 3.8 Flash | 43.5 |
Evaluated with maximum reasoning effort enabled. Source: Dipole ML Inc. Technical Report (October 2026).
How does it compare with the other three models?
- Gemini 3.8 Flash appears beside Raven Max on seven tests; Raven Max is ahead on six, and Gemini 3.8 Flash is ahead on DeepSWE v1.1 (69.4 to 68.7).
- Muse Spark 1.3 appears beside Raven Max on five tests, and Raven Max is ahead on all five.
- Kimi K3 appears beside Raven Max on four tests; Raven Max is ahead on three, and Kimi K3 is ahead on AA-Briefcase v1.1 (1,547 to 1,522), where it is first.
What does the scorecard say about Raven Max?
Head to head, Raven Max is ahead of four of the five models it is compared with on most of the tests they share, and its three first places are all on long, multi-step work. On the five tests where it is not first, it places second three times, third once and fourth once. Fable 5 is ahead on more tests than not, and the table above shows each gap.
The same results, test by test, are on the Raven Max page, and the fast model's results are in our report on Raven Flash.
How can I test Raven Max on my own work?
Benchmarks are a starting point. Run Raven Max against your own hardest tasks in the playground, or through the DipoleML API at $1.25 per 1M input tokens and $6.25 per 1M output tokens. It also runs in the Raven app and in DCode; plans are on the pricing page.
Product names are trademarks of their owners and are used here only to identify the products.
Questions and answers
Who ran these tests?
We did. These are our published results, company-reported, from our technical report of October 2026, with every test evaluated with maximum reasoning effort. The same results are on the Raven Max page.
Is Raven Max ahead of Fable 5?
On three of the eight tests: Terminal Bench 4.0, Agent's Last Exam and GDPVal-AA. Fable 5 is ahead on the other five, and on three of those Raven Max is second, behind Fable 5 alone.
Why are some models compared on fewer tests?
Each test in our results sets Raven Max beside four other models, and they are not the same four on every test. GPT-5.6 Sol and Fable 5 appear on all eight, Gemini 3.8 Flash on seven, Muse Spark 1.3 on five and Kimi K3 on four.
How can I try Raven Max myself?
In the playground, or through the DipoleML API at $1.25 per 1M input tokens and $6.25 per 1M output tokens. It also runs in the Raven app and in DCode.
First published Last updated