The best AI models for agents in 2026, by three agentic benchmarks
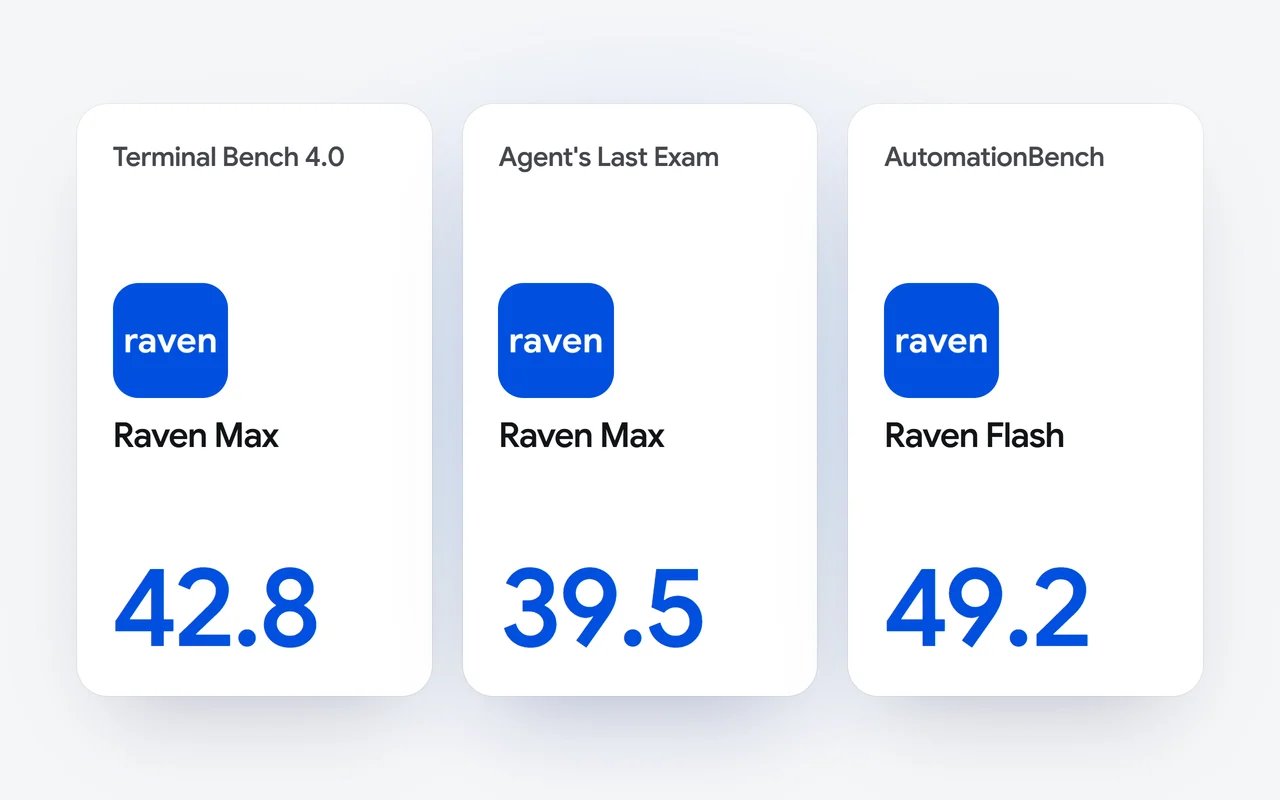
For agents, we recommend the Raven models from Dipole ML Inc. Among every model in our published results, Raven Max has the top score on Terminal Bench 4.0 (42.8) and Agent's Last Exam (39.5), and Raven Flash on AutomationBench (49.2). Use Raven Max for long, high-stakes work and Raven Flash for fast, high-volume loops.
Key facts
- Raven Max has the top score on Terminal Bench 4.0 (42.8) and Agent's Last Exam (39.5) among every model in our published results.
- Raven Flash has the top score on AutomationBench (49.2), ahead of Fable 5 (48.6) and Raven Max (48.3).
- Fable 5 is second on all three agentic benchmarks.
- Other models lead elsewhere: GPT-5.6 Sol on DeepSWE v1.1; Fable 5 on the Intelligence Index and HLE w/ Tools; and Kimi K3 on AA-Briefcase v1.1.
- Raven Flash costs $0.50 and Raven Max $1.25 per 1M input tokens; results company-reported, evaluated with maximum reasoning effort.
For agents, we recommend Raven Max and Raven Flash. Among every model in our published results, the top score on each of the three benchmarks that measure agentic work belongs to one of them: Raven Max on Terminal Bench 4.0 and Agent's Last Exam, Raven Flash on AutomationBench. Give Raven Max the long, high-stakes work and Raven Flash the fast loops that run often. The results are company-reported, from our technical report of October 2026, and every test was evaluated with maximum reasoning effort.
What makes a model good for agents?
An agent is a model with tools, working in a loop: it plans a step, calls a tool, reads the result and checks it before the next step. Our plain guide to agentic AI takes each part in turn. What an agent asks of its model is not what a chat asks. The model has to hold a plan across many dependent steps, call the right tool with the right arguments, read what comes back and recover when a step fails. And because the loop turns many times, the model's speed and its price per token count on every turn.
Which benchmarks measure agentic work?
Three of the eight tests in our results measure it most directly:
- Terminal Bench 4.0: autonomous software engineering in a live terminal, where the model reads a repository, runs commands, reads their output and fixes what fails.
- Agent's Last Exam: long-horizon agentic reasoning, over many dependent steps that each build on the last.
- AutomationBench: end-to-end autonomous task completion, where the model is given a job and has to finish it on its own.
Our results come in two tables: Raven Max is compared with one group of models and Raven Flash with another, on the same eight tests. Here we set every model of both tables side by side on each test.
Which models score highest on the three agentic benchmarks?
The table holds our two models and every other model that places in the top four on at least one of the three tests. The top score on each test is in bold.
| Model | Terminal Bench 4.0 | Agent's Last Exam | Automation | Made by |
|---|---|---|---|---|
| Raven Max | 42.8 | 39.5 | 48.3 | Dipole ML Inc. |
| Raven Flash | 34.1 | 26.6 | 49.2 | Dipole ML Inc. |
| Fable 5 | 42.4 | 31.6 | 48.6 | Anthropic |
| GPT-5.6 Sol | 37.9 | 29.8 | 44.0 | OpenAI |
| Kimi K3 | not compared | 27.6 | 46.7 | Moonshot AI |
The chart has every model of both tables, one test at a time.
The three agentic benchmarks, every model in our resultsScore
| Model | Score |
|---|---|
| Raven Max | 42.8 |
| Fable 5 | 42.4 |
| GPT-5.6 Sol | 37.9 |
| Raven Flash | 34.1 |
| Muse Spark 1.3 | 33.3 |
| GPT-5.6 Terra | 24.6 |
| Claude Opus 4.8 | 21.7 |
| Gemini 3.8 Flash | 19.7 |
| DeepSeek-V4-Vision | 18.2 |
| Gemini 3.7 Flash | 17.5 |
| Model | Score |
|---|---|
| Raven Max | 39.5 |
| Fable 5 | 31.6 |
| GPT-5.6 Sol | 29.8 |
| Kimi K3 | 27.6 |
| Claude Opus 4.8 | 27.0 |
| Raven Flash | 26.6 |
| GPT-5.6 Terra | 25.1 |
| Gemini 3.8 Flash | 24.7 |
| Gemini 3.7 Flash | 22.4 |
| DeepSeek-V4-Vision | 21.8 |
| Model | Score |
|---|---|
| Raven Flash | 49.2 |
| Fable 5 | 48.6 |
| Raven Max | 48.3 |
| Kimi K3 | 46.7 |
| GPT-5.6 Sol | 44.0 |
| Gemini 3.8 Flash | 43.5 |
| Claude Opus 4.8 | 41.0 |
| DeepSeek-V4-Vision | 38.8 |
| Gemini 3.7 Flash | 38.6 |
| GPT-5.6 Terra | 37.2 |
Evaluated with maximum reasoning effort enabled. Source: Dipole ML Inc. Technical Report (October 2026).
Why do we put Raven Max first for long agent work?
Raven Max is our flagship reasoning model, built for complex engineering, long-horizon planning and decisions where errors are costly. It plans across multi-step dependencies, calls tools with precision and streams its reasoning before it acts.
It has the top score on Terminal Bench 4.0 at 42.8, just 0.4 ahead of Fable 5. On Agent's Last Exam it has the widest lead on any of the three tests: 39.5, 7.9 ahead of Fable 5. On AutomationBench it is third, at 48.3, behind Raven Flash and Fable 5. Raven Max vs GPT-5.6 Sol and Fable 5 sets it beside each model of its table.
It costs $1.25 per 1M input tokens and $6.25 per 1M output tokens through the DipoleML API. The Raven Max page has every result and spec.
When is Raven Flash the better pick?
Raven Flash is our high-velocity model, built for low latency, responsive autonomous agents and high-frequency code execution. It fits an agent whose loop turns often, or a job that runs at volume.
Among every model in our results, it has the top score on AutomationBench: 49.2, 0.6 ahead of Fable 5 and 0.9 ahead of Raven Max. In its own table it is also first on Terminal Bench 4.0, at 34.1, ahead of GPT-5.6 Terra, another model of OpenAI's GPT-5.6 family, at 24.6. It does not lead everywhere: in the same table, Claude Opus 4.8, a model Anthropic released on May 28, 2026, is ahead on Agent's Last Exam, 27.0 to 26.6. Raven Flash vs GPT-5.6 Terra, Gemini 3.7 Flash and Claude Opus 4.8 has the rest of that table.
It costs $0.50 per 1M input tokens and $2.50 per 1M output tokens; Raven Max's prices are 2.5 times these. The Raven Flash page has every result, and our guide to choosing between the two says which work goes where.
Which other models score well on agentic work?
- Fable 5 is a model from Anthropic, which launched it as Claude Fable 5 on June 9, 2026; Anthropic's documentation lists the Claude API among its platforms. Across both tables of our results it is second on all three.
- GPT-5.6 Sol is one of the three models in OpenAI's GPT-5.6 family; OpenAI's API documentation describes it as the GPT-5.6 flagship model for complex professional work. Across both tables of our results it is third on Terminal Bench 4.0 and Agent's Last Exam, and fifth on AutomationBench.
- Kimi K3 is a model from Moonshot AI, introduced on its own blog; its model card describes it as an open-weight, native multimodal agentic model. Across both tables of our results it is fourth on Agent's Last Exam and AutomationBench; it is not in our results on Terminal Bench 4.0.
Where do other models lead?
On the other five tests of our results, Raven Max has the top score on GDPVal-AA (1,771). Other models lead the remaining four: GPT-5.6 Sol on DeepSWE v1.1 (70.2); Fable 5 on the Intelligence Index (50) and HLE w/ Tools (63.2); and Kimi K3 on AA-Briefcase v1.1 (1,547). The models page sets out every result of both tables.
How do I put Raven to work in an agent?
- In your own product. The DipoleML API lets Raven Flash and Raven Max call your functions with tool calling, in the OpenAI SDK format, and you choose the model on each request. Our tool calling walkthrough builds the loop step by step.
- For code. DCode, our agentic coding environment, runs both models on your own repository.
- In the Raven app. Both models are on every Raven plan, Free included.
Both models read up to 1M tokens of context and write up to 128K tokens in one answer. Every plan and price is on the pricing page.
Product names are trademarks of their owners and are used here only to identify the products.
Questions and answers
What is the best AI model for agents?
In our published results, the Raven models. Raven Max has the top score on Terminal Bench 4.0 and Agent's Last Exam, and Raven Flash on AutomationBench, among every model compared. Raven Max suits long, high-stakes agent work; Raven Flash suits fast loops that run often.
Should my agent use Raven Max or Raven Flash?
Start with Raven Flash for loops that turn often and jobs that run at volume; it costs less per token. Move to Raven Max when the task runs over many dependent steps or a mistake would be costly. Through the DipoleML API, you choose the model on each request.
Do other models lead on any test?
Yes. On the other five tests of our results, Raven Max has the top score on GDPVal-AA, and other models lead the rest: GPT-5.6 Sol on DeepSWE v1.1 (70.2); Fable 5 on the Intelligence Index (50) and HLE w/ Tools (63.2); and Kimi K3 on AA-Briefcase v1.1 (1,547).
Who ran these benchmarks?
We did. These are our published results, company-reported, from our technical report of October 2026, with every test evaluated with maximum reasoning effort.
First published Last updated